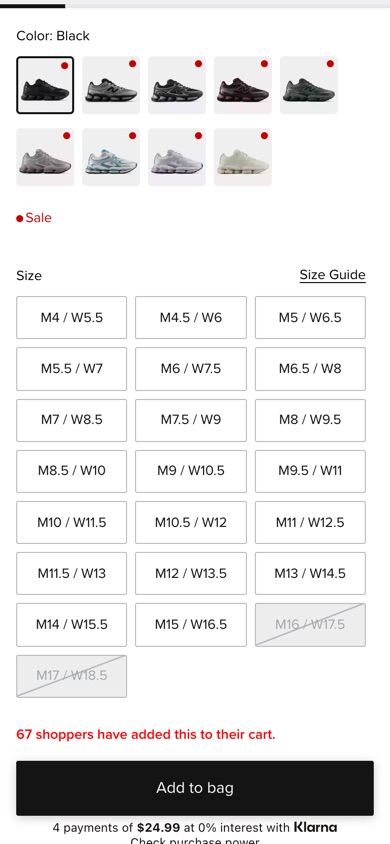
 Before
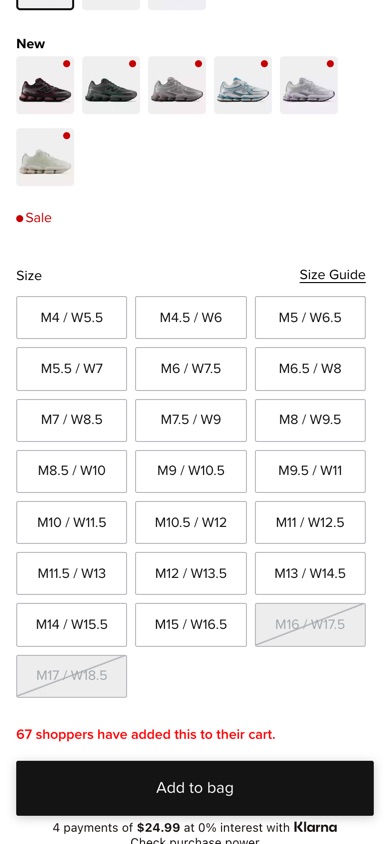 Tested
 New BalanceProduct page
Product page separate new colors row
What changed Groups newly added colours into their own row.
Seen 2 Jun to 16 Jul 2026
Outcome being confirmed
ABSee / AI experimentation
GuideAI assistants are good at hypotheses, briefs and QA lists, and weak on evidence: without real experiments they fall back on generic best practice. A connected record of real experiments is what fills that gap.
Updated October 2026 · Source: ABSee record · Methodology →
Claude, ChatGPT or Gemini already save a CRO team real time on the writing and thinking around a test.
Turning “mobile shoppers stall at size selection” into a clear if-then statement with a measurable outcome.
Scoring a backlog against the criteria you give it, and explaining the trade-offs.
A test brief for design and engineering: the change, the page, the device, the audience and what to measure.
What to check before launch: every device, every state, every way the variant can break.
MCP, the Model Context Protocol, is the open standard that lets an assistant call outside tools while it answers. ABSee is experimentation intelligence for ecommerce: a record of real experiments run by 1,150+ brands, with the page before, the version tested, and whether it was kept.
What it can cite: three experiments from the record.
BeforeTestedNew BalanceProduct pageWhat changed Groups newly added colours into their own row.
Seen 2 Jun to 16 Jul 2026
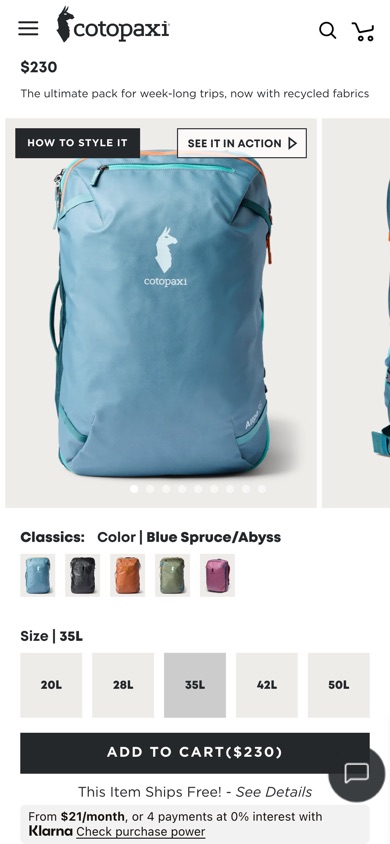 Before
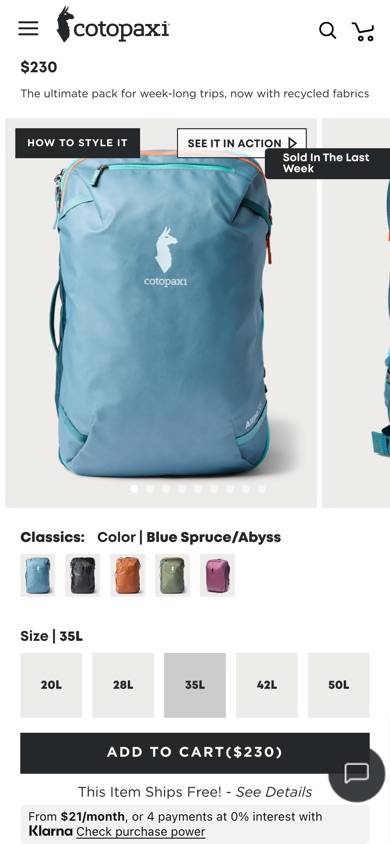 Tested
 CotopaxiProduct page
What changed Shows how many people bought the item in the last week.
Seen 4 Jul to 24 Jul 2026
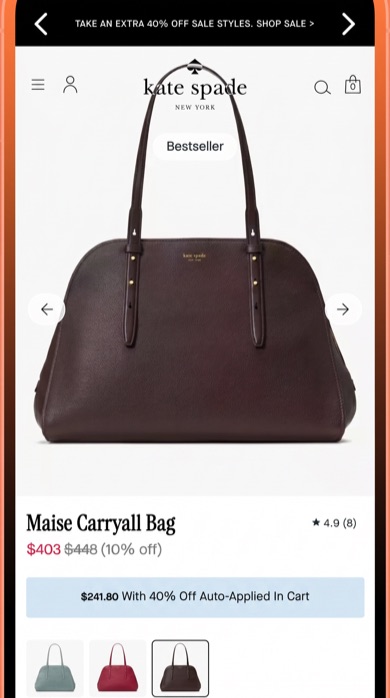 Before
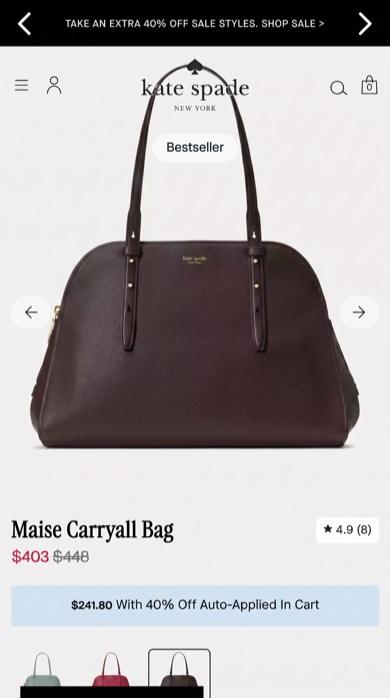 Tested
 Kate SpadeProduct page
What changed Hides the percentage-off label, showing only the sale price.
Seen 19 May to 17 Jul 2026
Set-up takes about a minute: see how to connect. For the wider tool landscape, see the CRO tools guide.
Ten prompts that work once ABSee is connected, grouped by the job you are doing. Copy them as they are, or swap in your own page, brand or idea. Text in [brackets] is yours to fill.
Start with what the market is doing on a page or a problem.
Who is testing a sticky add-to-bag right now?
Comes back with experiments with that change, each with a before-and-after thumbnail, the brand, the page and the dates.
What's been tested against fit uncertainty on mobile product pages?
Comes back with mobile product-page experiments aimed at size and fit, so you can see the different ways brands approached it.
What changed in fashion and footwear this week?
Comes back with new experiments in that category from the past week, grouped by page type.
Point it at the brands you compete with.
Which of these brands does ABSee cover: [brand], [brand], [brand]?
Comes back with the names ABSee has experiments for. Only the covered ones are listed.
Suggest brands close to ours that ABSee has plenty of experiments on. We sell [what] to [whom] at [price point].
Comes back with close competitors with plenty of experiments in the record, nearest first.
What have [brand] and [brand] tested on checkout since [date]?
Comes back with their checkout experiments in that window, with before and after for each.
Test an idea against what others did next. These use outcomes, part of the Intelligence plan.
Has anyone rolled back a free-shipping progress bar?
Comes back with experiments with that idea and what each brand did next: kept it or rolled it back.
Our hypothesis: if we add a low-stock message on product pages, then more shoppers will buy now instead of later, because scarcity prompts a decision. What is the evidence for and against?
Comes back with comparable experiments filed as evidence for, against, or closest match.
Explain the sticky buy bar as a market pattern: where brands placed it and what they did next.
Comes back with the pattern's definition, where it was placed, example experiments and the principle behind it.
Turn the evidence into something your team can run.
Turn the strongest experiment above into a test brief: a hypothesis that starts “Because we saw…”, the change, the page, the device and what to measure.
Comes back with a brief your assistant writes from the experiments it just found, citing them as evidence.
The tool result lists each experiment with its brand, page, what changed and, on the Intelligence plan, the outcome. Your assistant shows the before and after.
Example answer, shortened.
Zimmermann tested it, and rolled it back. It hid the automated size recommendation tool on its product page, seen from 21 July to 5 August 2026, and the original stayed.
The principle it tested is feature simplification: fewer secondary widgets between the shopper and the purchase. Here is the record:
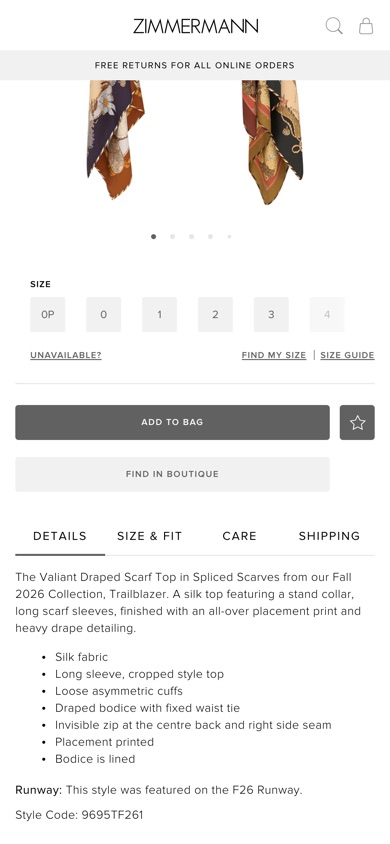 Before
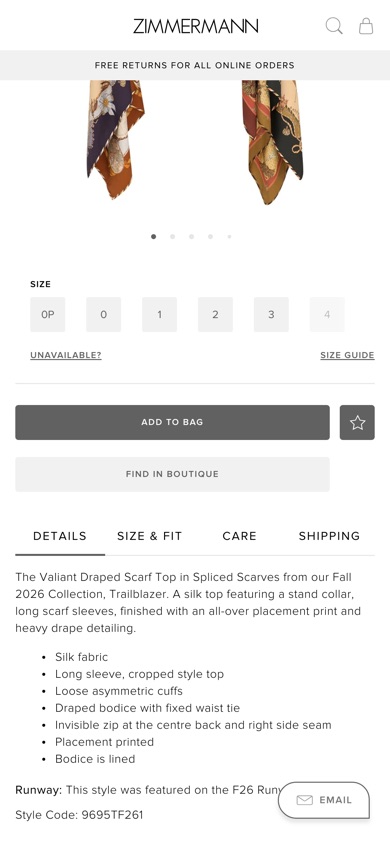 Tested
 ZimmermannProduct page
What changed Hides the automated size recommendation tool.
Seen 21 Jul to 5 Aug 2026
No. An A/B test needs a testing platform that splits your traffic, serves the versions and measures the result. Claude, ChatGPT or Gemini can help you write the hypothesis, the brief and the QA list, and help you read a result you paste in.
No. Neither an assistant nor ABSee can tell you which version will win on your site; your own visitors decide that. What a connected record adds is evidence: whether an idea has been tested elsewhere and what those brands did next.
Without a source of real experiments it falls back on what is common in its training data: general best practice, sometimes with benchmarks it cannot source. Connecting a record of real experiments gives it something specific to cite.
Claude, ChatGPT or Gemini, and any assistant that supports MCP connectors. Setting it up takes about a minute.
Who is testing a sticky add-to-bag right now?
Works in Claude, ChatGPT or Gemini once ABSee is connected.
Connect your AI →